True predictive power in banking isn’t derived from esoteric AI models, but from an infrastructure meticulously engineered to prevent catastrophic financial and regulatory failures.
- Unstructured « dark data » is a direct, quantifiable liability, not a future asset waiting to be monetised.
- Data architecture failures, such as unmonitored transaction flows, are not abstract risks; they can directly result in multi-billion-dollar regulatory penalties.
Recommendation: Shift focus from generic « big data » collection to disciplined « liability engineering » by implementing rigorous data cleansing, advanced privacy-enhancing technologies, and aggressive, logic-based ethical hacking.
For Chief Data Officers within the UK’s financial institutions, the paradox is palpable. You are stewards of petabytes, yet starved of actionable intelligence. The promise of data-driven strategy remains elusive, buried under the sheer mass of raw transactional logs, legacy system outputs, and unstructured customer interactions. The common discourse revolves around adopting more AI and migrating to the cloud, treating technology as a panacea. This approach, however, fundamentally misunderstands the core of the problem and exposes the institution to monumental risk.
The prevailing wisdom suggests that amassing data is the primary goal, and its value will magically materialise later. This has led to sprawling data swamps that are not only expensive to maintain but also constitute a significant compliance and security liability. The real challenge isn’t acquiring more data; it’s architecting a system that can reliably, swiftly, and safely extract statistically significant behavioural trends from the data you already possess. This isn’t a matter of simply plugging in a new software solution.
This article deviates from the high-level platitudes. We will not discuss the ‘potential’ of AI. Instead, we will dissect the specific, high-cost architectural and procedural failures that transform data assets into liabilities. The central thesis is that a successful predictive analytics programme is built not on a foundation of optimistic technology adoption, but on a rigorous, almost pessimistic, practice of liability engineering. It’s about systematically eliminating the failure points that lead to flawed models, privacy breaches, and catastrophic regulatory fines. We will explore the mathematical and architectural principles required to build a resilient, high-performance analytics engine that generates profit, not just insights.
This analysis will proceed logically, from the foundational problem of data storage and cleansing to the advanced architectural and security considerations essential for operating at scale in a high-stakes regulatory environment. Each section addresses a critical failure point that can derail any data-centric initiative.
Summary: From Terabytes to Tangible ROI: A Data Scientist’s Blueprint for Predictive Retail Banking Analytics
- Why Storing Terabytes of Unstructured Information Is Costing Millions Without Yielding ROI?
- How to Cleanse and Standardise Transactional Histories for Machine Learning Processing?
- Hadoop vs Snowflake: Which Architecture Processes Millions of Daily Swipes Quicker?
- The Anonymisation Failure That Breaches Customer Privacy During Algorithmic Training
- Slashing Query Times on Massive Tables Using Advanced Data Partitioning
- The Data Migration Oversight That Triggers Immediate GDPR Penalties
- Why Relying Solely on Automated Vulnerability Scanners Misses Critical Business Logic Flaws?
- Executing Aggressive Ethical Hacks to Fortify Corporate Financial Networks
Why Storing Terabytes of Unstructured Information Is Costing Millions Without Yielding ROI?
The foundational error in many financial institutions’ data strategy is the hoarding of « dark data »—information collected, processed, and stored but never used for analytics, business intelligence, or decision-making. This includes vast swathes of transactional histories, archived reports, and server logs. Far from being a latent asset, this data represents a pure cost centre and a significant source of risk. The cost is not merely confined to storage hardware or cloud service subscriptions; it encompasses energy consumption, management overhead, and the opportunity cost of capital that could be deployed elsewhere. Critically, this data often falls outside of active governance, making it a fertile ground for security vulnerabilities and compliance breaches.
The scale of this issue is not trivial. Comprehensive analysis reveals that, within the financial sector, an estimated 52% of all data collected remains unused for any strategic purpose. This digital landfill is not static; it grows with every transaction and interaction. The financial implications are staggering. If current trends continue, global dark data storage costs are projected to create a multi-billion-dollar hole in corporate budgets, a figure that is entirely divorced from any return on investment. The first principle of a sound data strategy is therefore not acquisition, but a ruthless and continuous audit of data utility. Information without a clear, testable hypothesis for value creation is a liability.
From a data science perspective, this unstructured, un-governed data is worse than useless; it is poisonous. Its presence complicates data discovery, pollutes training datasets with irrelevant or low-quality information, and dramatically increases the computational load for any exploratory analysis. Before any predictive modelling can begin, the first step is to quarantine and evaluate this dark data. The goal is to establish a clear line of demarcation: data that is actively managed and integrated into the analytics lifecycle, and data that is archived under strict, low-cost retention policies or, ideally, defensively deleted. Treating storage as infinite and free is an architectural fallacy that has already cost the industry billions.
How to Cleanse and Standardise Transactional Histories for Machine Learning Processing?
Once the digital clutter of dark data has been addressed, the next, non-negotiable phase is the rigorous cleansing and standardisation of the remaining transactional data. Machine learning algorithms, particularly those used for predictive analytics like fraud detection or credit risk scoring, are mathematically sensitive to the quality and consistency of their input. Feeding raw, un-cleansed data into a model is the equivalent of performing surgery with unsterilised instruments: the outcome is unpredictable and likely catastrophic. Inconsistencies in data formats, missing values, outliers, and varied categorical encodings (e.g., ‘U.K.’, ‘UK’, ‘United Kingdom’) can introduce significant bias and variance, rendering any resulting predictions useless at best and dangerously misleading at worst.
A robust methodology for this process is the Medallion Architecture, a multi-layered approach to building a data lakehouse that progressively refines data. This framework provides a clear path from raw ingestion to analytics-ready, high-value data assets.
Case Study: Medallion Lakehouse for Consolidated Banking Data
A forward-thinking banking client successfully implemented a medallion lakehouse architecture to unify fragmented data from electronic banking, mobile apps, and even social media interactions. The architecture consists of three distinct layers. The Bronze layer ingests raw, unaltered data from sources like JSON files and RDBMS, serving as a historical archive. The Silver layer is where the real work of cleansing, validation, and standardisation occurs, creating an enforced schema and a single source of truth. Finally, the Gold layer aggregates and prepares this clean data into business-ready tables for specific analytics use cases like credit risk assessments and real-time customer segmentation. This structured approach led to significant cost savings in data management and, more importantly, enabled faster, more reliable decision-making.
The standardisation process must be algorithmically driven and auditable. This involves defining a canonical data model for key entities like customers, accounts, and transactions. Scripts must be developed to handle missing data through principled imputation (e.g., mean, median, or model-based imputation), normalise numerical features to a common scale (e.g., Z-score normalisation), and consistently encode categorical variables (e.g., one-hot encoding). This is not a one-time task but a continuous process that must be integrated into the data ingestion pipeline to ensure ongoing data integrity.
Action Plan: Implementing a Data Cleansing Pipeline
- Points of contact: Catalogue every single data source feeding transactional histories (e.g., core banking system APIs, payment gateway logs, mobile app event streams).
- Collecte: Inventory existing data assets and create a data dictionary defining every field, its expected format, and acceptable value range (e.g., Transaction_Amount: Numeric, >0).
- Cohérence: Develop validation rules to automatically flag or quarantine records that violate the data dictionary (e.g., invalid date formats, non-standard country codes).
- Mémorabilité/émotion: Profile the data to identify outliers and anomalies. Distinguish between data errors (e.g., a transaction date in the future) and genuine, rare events (e.g., a high-value fraudulent transaction).
- Plan d’intégration: Design and implement an automated ETL/ELT pipeline that systematically applies cleansing and standardisation rules as data moves from Bronze to Silver layers. Prioritise the most critical data fields first.
Hadoop vs Snowflake: Which Architecture Processes Millions of Daily Swipes Quicker?
The debate between data processing architectures—traditionally dominated by on-premise Hadoop clusters versus modern cloud-native platforms like Snowflake—is often framed incorrectly. The question is not simply which is « faster, » but which provides the optimal Economic Query Velocity. This metric considers not just raw processing speed but also total cost of ownership, scalability, and the reduction in developer and analyst friction. For retail banking, which deals with millions of discrete, high-frequency events daily, the architectural choice has profound implications for the feasibility of real-time predictive analytics.
Hadoop, with its HDFS and MapReduce paradigm, offered a revolutionary approach to distributed storage and batch processing. However, its operational complexity, significant management overhead, and a rigid coupling of storage and compute have made it a less agile choice for the dynamic workloads of modern finance. Cloud-native data lakehouse platforms, in contrast, decouple storage and compute. This allows for independent scaling; you can spin up massive compute clusters for a few hours to handle a complex model training job and then scale them down to zero, paying only for the resources used, while the data resides in cheap object storage.
This decoupling is particularly crucial for the varied query patterns in banking analytics. A small team of data scientists might run complex, resource-intensive queries for model development, while hundreds of business analysts run lighter, more frequent BI queries. In a Snowflake-like architecture, these workloads can run concurrently on isolated virtual warehouses without competing for resources, ensuring that a long-running exploratory query doesn’t grind the C-suite’s dashboard to a halt. A major German bank’s modernisation is a case in point, where migrating to a cloud-based Data Lakehouse Platform resulted in a 50% reduction in infrastructure management costs while simultaneously creating an AI-ready foundation for MLOps.
Furthermore, modern platforms are increasingly leveraging specialised hardware to accelerate performance beyond what general-purpose CPUs can offer. For the vector and matrix operations that are the bedrock of machine learning, this is a game-changer.
The use of GPU-accelerated data processing can slash query times for complex analytical tasks from hours to minutes or even seconds. As shown by the intricate pathways on a modern processing chip, these architectures are purpose-built for the parallel computation required to sift through massive datasets. For a financial institution, this isn’t just about speed; it’s about the ability to ask more complex questions of your data, iterate on models faster, and ultimately, get closer to real-time predictive capability.
The Anonymisation Failure That Breaches Customer Privacy During Algorithmic Training
A critical, and often misunderstood, failure point in banking analytics is the reliance on naive anonymisation techniques. Simply hashing or removing direct personal identifiers (name, address) is demonstrably insufficient to protect customer privacy. In a high-dimensional dataset like a transactional history, combinations of seemingly innocuous data points—such as transaction time, amount, and merchant location—can be used to re-identify individuals with alarming accuracy. This is known as a linkage attack, and its success constitutes a severe data breach, with all the attendant regulatory and reputational consequences. The financial cost of such a failure is not hypothetical; according to IBM’s analysis, the average cost of a data breach in the financial sector is a staggering USD 6.08 million, 22% higher than the global average.
The mathematical reality is that traditional anonymisation fails because it doesn’t protect against what an adversary already knows. If an attacker knows that a certain individual made a specific purchase on a given day, they can search the « anonymised » dataset for that pattern and deanonymise the individual’s entire transaction history. This vulnerability invalidates any model trained on such data and places the institution in direct violation of privacy regulations like GDPR.
The solution requires a more sophisticated, mathematically rigorous approach known as Privacy-Enhancing Technologies (PETs). The gold standard among these is Differential Privacy. Instead of trying to anonymise the data itself, differential privacy adds a carefully calibrated amount of statistical noise to the queries run against the data. It provides a mathematical guarantee that the output of any analysis will be statistically indistinguishable whether any single individual’s data is included or not. This makes it impossible to infer anything specific about an individual from the model’s output. A powerful extension of this is the creation of synthetic data that adheres to these principles.
As leading researchers in the field have noted, this method provides a scalable path forward for data-driven industries. Zinan Lin et al. from Carnegie Mellon University state it clearly in their work on the subject:
Generating differentially private synthetic data that closely resembles the original private data is a scalable way to mitigate privacy concerns in the current data-driven world.
– Zinan Lin et al., Differentially Private Synthetic Data via Foundation Model APIs 1: Images
For a financial institution, this means data scientists can train models on high-fidelity synthetic data that retains the statistical properties of the original dataset without ever exposing sensitive customer information. This is not just a compliance checkbox; it is a fundamental principle of liability engineering in the age of algorithmic decision-making.
Slashing Query Times on Massive Tables Using Advanced Data Partitioning
Even on the most powerful hardware, running queries against a single, monolithic table containing billions of transaction records is computationally inefficient and economically unviable. When an analyst queries for a specific customer’s activity over the last month, the database should not have to scan years of data for every customer in the institution. This is where advanced data partitioning becomes a critical performance lever. Partitioning is the technique of physically dividing a large table into smaller, more manageable pieces, while still treating it as a single logical entity. When a query is executed, the database’s query optimizer can use a feature called ‘partition pruning’ to scan only the relevant partitions, dramatically reducing I/O and CPU load.
For a typical banking transaction table, several partitioning strategies can be employed, often in combination. The most common is range partitioning on the transaction date. By partitioning the table by month or by quarter, a query for recent activity will only touch the most recent, « hot » partitions, ignoring terabytes of historical « cold » data. For example, a table could be structured with partitions like `transactions_2024_Q1`, `transactions_2024_Q2`, etc. This aligns perfectly with the temporal nature of most financial analysis.
A second, complementary strategy is hash partitioning on a key like `CustomerID`. This strategy distributes data evenly across a set number of partitions based on a hash function applied to the customer ID. The benefit here is that it prevents « hot spots » where a few highly active customers could cause one partition to become disproportionately large. When a query filters by a specific `CustomerID`, the query optimizer can immediately identify the single partition that contains all data for that customer, again pruning all others.
Finally, for more complex use cases, list partitioning can be used on a categorical column like `TransactionType` (e.g., ‘Credit’, ‘Debit’, ‘Transfer’). This allows queries that aggregate data for a specific type of transaction to run exceptionally fast. The true power comes from composite partitioning, such as range partitioning by date and then hash sub-partitioning by `CustomerID`. This creates a highly optimised physical data structure that allows the database engine to navigate directly to the small sliver of data required by a query, slashing query times from hours to seconds and unlocking the potential for interactive, exploratory analytics on a massive scale.
The Data Migration Oversight That Triggers Immediate GDPR Penalties
Data migration projects—whether moving from a legacy system to a new one, or from an on-premise data centre to the cloud—are often viewed as purely technical IT projects. This is a catastrophic miscalculation. In the context of financial services, every data migration is a high-risk regulatory event. A single oversight in maintaining the chain of custody or ensuring data provenance can create regulatory blind spots that mask illicit activity, leading to fines that can cripple an institution. The General Data Protection Regulation (GDPR) and anti-money laundering (AML) directives are not forgiving of such architectural failures.
A migration is not merely a copy-paste operation. It involves transforming data schemas, validating data integrity post-transfer, and, most critically, ensuring that all regulatory monitoring and reporting capabilities are maintained or enhanced. The failure to do so can have devastating consequences. The case of TD Bank serves as a stark, multi-billion-dollar warning. The bank agreed to pay over $3 billion in penalties for systemic failures in its AML programme. The root cause was a data architecture failure: a staggering 92% of the bank’s total transaction volume—$18.3 trillion in activity—went unmonitored for six years due to data being locked in closed SaaS applications and broken chains of custody at extraction boundaries.
This illustrates the principle of regulatory data integrity with brutal clarity. The ability to monitor, audit, and report on data is as important as the data itself. During any migration, a parallel audit trail must be established. This involves checksums to verify data has not been altered, record counts to ensure no data was dropped, and sampling-based validation to confirm that business logic remains intact after transformation. The entire process must be transparent to regulators and internal auditors, with clear documentation of how data flows from source to destination.
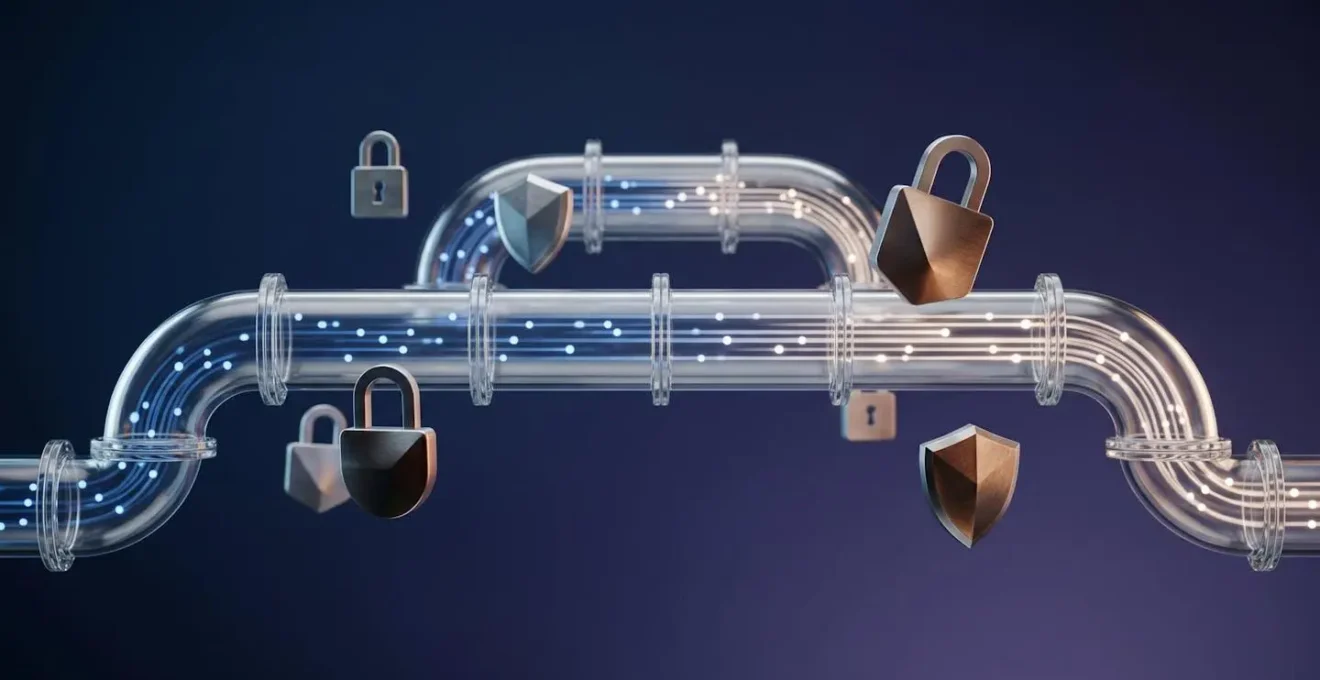
A secure migration architecture, as conceptually illustrated above, is not an abstract ideal but a concrete necessity. It visualises data flowing through a secured pipeline, with each stage subject to verification and logging. The « locks » and « shields » represent the automated compliance checks and audit points that must be built into the migration workflow. Treating migration as an afterthought or a simple technical task, as opposed to a core component of your risk and compliance framework, is an invitation for regulatory disaster.
Key takeaways
- Dark data is not a future asset but a current liability; its storage cost and risk profile demand active management or defensive deletion.
- The Medallion Architecture (Bronze, Silver, Gold) provides a structured, auditable framework for cleansing raw data into analytics-ready assets.
- Modern cloud data platforms offer superior « Economic Query Velocity » by decoupling storage and compute, enabling flexible, cost-effective scaling for varied analytical workloads.
Why Relying Solely on Automated Vulnerability Scanners Misses Critical Business Logic Flaws?
In the world of cybersecurity, there is a dangerous over-reliance on automated vulnerability scanners. These tools are effective at identifying known software vulnerabilities, misconfigurations, and missing patches—the low-hanging fruit of security. While necessary, they are fundamentally incapable of detecting a more insidious class of threats: business logic flaws. These are vulnerabilities that arise not from a technical bug in the code, but from an exploitable loophole in the rules that govern the application’s intended behaviour. For a financial institution, these are the most dangerous vulnerabilities of all.
An automated scanner can check if a server is running an outdated version of Apache, but it cannot understand what a « wire transfer » is. It cannot reason about the multi-step process required to approve a loan or the business rules governing interest calculation. Therefore, it cannot detect an attack that exploits these rules. For example, an attacker might discover that they can initiate a transfer, then cancel it in a specific way that causes the system to fail « open, » crediting their account without debiting the source. Or they might find a way to manipulate a sequence of small deposits and withdrawals across multiple accounts to confuse an AML monitoring system.
These are asymmetric vulnerabilities; they are difficult for a machine to find but often intuitive for a creative human adversary to uncover. The flaw isn’t in a line of code, but in the assumptions made when the business process was designed. A classic example is a flaw in a rewards program where a user can repeatedly perform an action that earns points and then reverse the action without the points being clawed back, allowing for infinite point generation. An automated scanner has no concept of « points » or « fairness »; it will never find this flaw. Similarly, it cannot detect if an attacker can manipulate API calls to bypass a credit check or apply for the same loan multiple times before the system’s state is updated.
This highlights a critical gap in many corporate security postures. The focus on technical vulnerabilities, while important, creates a false sense of security. The most damaging attacks on financial systems are often those that don’t « break » the code but instead abuse its logic. Protecting against these requires a shift in mindset from purely technical scanning to process-oriented, human-driven analysis.
Executing Aggressive Ethical Hacks to Fortify Corporate Financial Networks
The only effective defense against a creative, logic-driven attacker is to adopt their mindset. This is the purpose of aggressive ethical hacking, also known as penetration testing. Rather than passively scanning for known vulnerabilities, this practice involves actively attempting to exploit the system’s business logic to achieve a malicious outcome, such as illicitly transferring funds or gaining access to sensitive customer data. It moves beyond checking for technical flaws and instead asks, « How can this system be abused? » This proactive, offensive approach is the most reliable way to identify and remediate the business logic flaws that automated scanners miss.
An effective ethical hacking engagement for a financial network is not a generic checklist exercise. It involves a « Red Team » of security professionals who are given a specific objective—for example, « Exfiltrate the transaction history of a high-net-worth individual without triggering an alert. » The team then uses a combination of technical exploitation, social engineering, and, most importantly, deep analysis of the application’s business processes to achieve this goal. They will probe for race conditions in transaction processing, attempt to manipulate currency conversion rates, and look for ways to subvert multi-factor authentication flows. Every failure of the system to prevent their attack is a critical vulnerability that must be fixed.
The value of this approach is being reflected in broader industry trends. While the threat of attacks like ransomware remains high, strong defensive measures are having a tangible impact. Recent data from the US Treasury’s Financial Crimes Enforcement Network (FinCEN) indicates that while the number of ransomware incidents remains high, the reported value of payments to attackers has shown a significant decrease. This proactive hardening of financial networks, driven by practices like aggressive ethical hacking, makes attacks more difficult and less profitable, contributing to a more resilient ecosystem.
Ultimately, fortifying a financial network is not a defensive game. You cannot simply build a wall and expect it to hold. You must constantly test that wall from the outside, with the same tools and creativity that your adversaries will use. Executing regular, objective-driven ethical hacks is not a security expense; it is an investment in understanding your true risk posture and a non-negotiable component of modern liability engineering.
The transition from a reactive, data-hoarding institution to a proactive, insight-driven one requires a fundamental shift in architecture, process, and culture. To begin this transformation, the logical next step is a comprehensive audit of your current data architecture against these principles of liability engineering and regulatory integrity.