The primary failure of most e-commerce dashboards is their function as a data repository rather than a decision engine.
- Effective dashboards ruthlessly limit primary KPIs to 3-5 core profit drivers to eliminate decision paralysis.
- System integrity, achieved through real-time data pipelines and consolidated databases, is prioritised over aesthetic complexity.
Recommendation: Audit your existing dashboards not for the data they display, but for the specific, profitable actions they fail to trigger.
For e-commerce directors and COOs in the UK retail sector, the promise of « data-driven decision-making » has morphed into a state of perpetual data fatigue. The landscape is saturated with dashboards displaying dozens of metrics, from session duration to social media likes. This approach, however, is fundamentally flawed. It treats the executive’s brain as a passive processor, expecting it to find the signal in an ever-increasing volume of noise. The result is not clarity, but paralysis—an inability to distinguish between trivial fluctuations and critical business threats.
The conventional wisdom of tracking more KPIs is a direct path to operational inefficiency. While connecting every available data source seems logical, it often leads to cluttered interfaces that obscure the most vital information. The true challenge is not data collection, but ruthless curation and architectural intelligence. It requires shifting the objective from displaying information to engineering specific actions.
But what if the solution was not to add another chart, but to remove ten? This is the core principle of an executable dashboard: a minimalist, high-velocity interface designed to eliminate cognitive load and link data directly to operational commands. It is less a window into the business and more a control panel for it.
This article deconstructs the architectural principles required to build such a system. We will move beyond the superficial discussion of which KPIs to track and instead focus on the structural foundations: cognitive science in layout design, data pipeline integrity for real-time accuracy, and the organisational strategies needed to break down the data silos that corrupt the entire system.
The following sections provide a blueprint for transforming your data displays from passive reports into active decision engines. From the psychological limits of human attention to the technical architecture of data consolidation, this guide outlines the critical components of a truly executable e-commerce dashboard.
Summary: Building Executable KPI Dashboards for E-Commerce Directors
- Why Displaying More Than 7 Metrics on a Single Screen Paralyses Decision-Making?
- How to Connect Shopify API Directly to Tableau for Real-Time Sales Tracking?
- Historical Lookback vs Predictive Forecasting: What Belongs on the Home Tab?
- The Vanity Metric Trap That Distracts Teams From Actual Profit Margins
- Fixing Data Refresh Delays That Cause Out-of-Stock Inventory Disasters
- Why Departmental Data Silos Cause Severe Billing Discrepancies?
- Why Manual Data Entry Between Departments Kills 30% of Qualified Leads?
- Consolidating Fragmented Software Databases for UK Enterprise Operations
Why Displaying More Than 7 Metrics on a Single Screen Paralyses Decision-Making?
The fundamental flaw in most executive dashboards is the violation of a core principle of cognitive psychology: Miller’s Law. This principle posits that the average person can only hold about seven items in their working memory at one time. When a dashboard presents 15, 20, or even 30 metrics simultaneously, it doesn’t empower the director; it overloads their cognitive capacity. This overload forces the brain to expend energy simply processing the display, leaving less capacity for the actual task of analysis and decision-making. The outcome is decision paralysis, where the user either defaults to ignoring the data or focuses on one or two familiar but potentially irrelevant metrics.
Research into cognitive load confirms this phenomenon directly. In dashboard environments, information overload leads to 58.7% slower decision-making compared to minimalist, well-structured interfaces. An executable dashboard, therefore, is an exercise in intentional restraint. Its primary screen must be engineered to present only the most critical, Tier 1 KPIs—typically no more than three to five—that represent the absolute health of the business, such as net profit margin, customer lifetime value (CLV), and average order value (AOV).
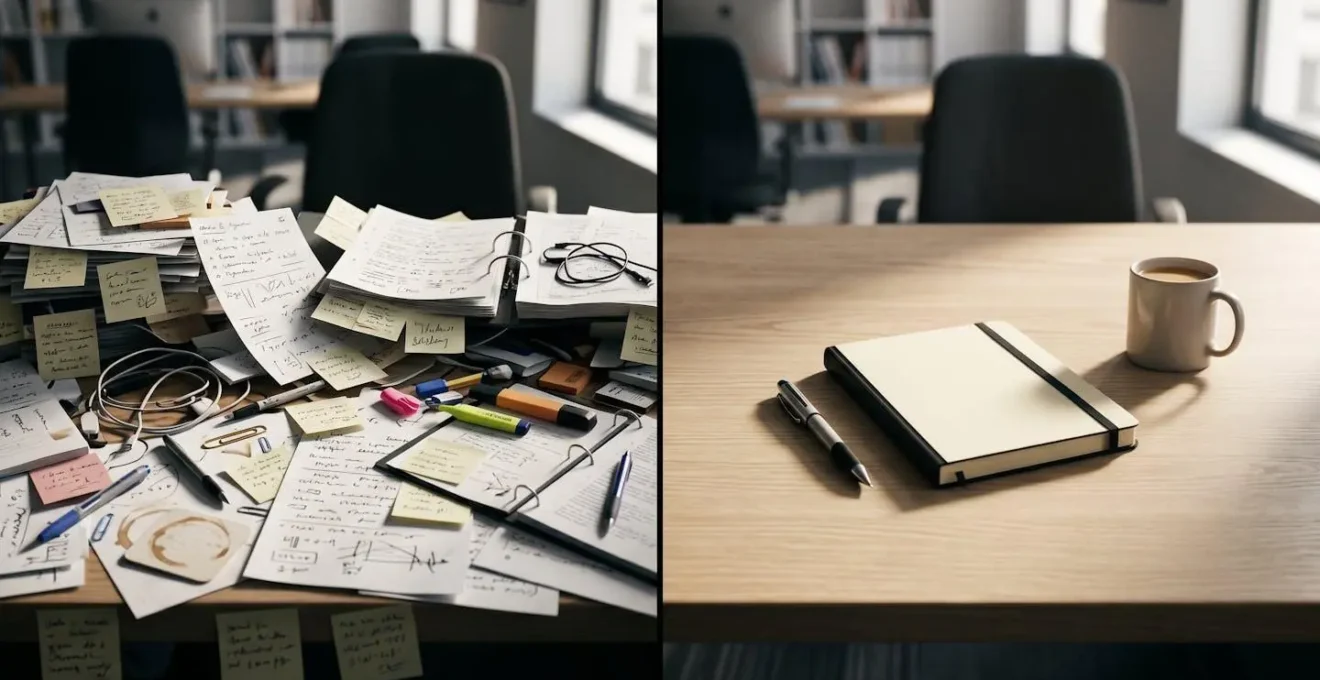
As the comparison shows, clarity is not achieved through aesthetic appeal alone, but through architectural reduction. All other metrics, known as diagnostic or Tier 2 KPIs, should not be discarded but organised logically into secondary views. The use of progressive disclosure—where details are revealed only upon user request via drill-downs, hovers, or expandable sections—is the key technical implementation. This keeps the primary view clean and actionable, transforming the dashboard from a cluttered data dump into a focused decision-making tool.
How to Connect Shopify API Directly to Tableau for Real-Time Sales Tracking?
Once the dashboard’s design philosophy is established, the next architectural challenge is creating a robust, low-latency data pipeline. For UK retailers using Shopify and Tableau, achieving real-time data flow is critical for inventory management and campaign agility. Simply exporting CSVs is not a viable solution for any serious operation due to inherent delays and the risk of manual error. A direct, automated connection is mandatory. There are several architectural approaches to this, each with distinct trade-offs in complexity, cost, and real-time capability.
The native Shopify API, while accessible, has rate limits that make it unsuitable for large stores with high order volumes. A more modern and scalable solution involves using a connector that leverages the OData (Open Data Protocol). As demonstrated by the Alpha Serve Tableau connector, this approach enables direct data refresh capabilities for both Tableau Cloud and Server without requiring a bridge. This is crucial for automation, allowing for scheduled refreshes that can handle thousands of daily orders and provide near real-time insights into product performance without manual intervention.
The choice of integration method depends entirely on operational scale and in-house technical resources. A structured comparison clarifies the best path forward.
| Method | Real-Time Capability | Technical Complexity | Best For |
|---|---|---|---|
| Direct API (Native) | Limited by rate limits | High | Small stores (<1000 orders/day) |
| OData Connector | Near real-time (15 min refresh) | Medium | Mid-size operations |
| Data Warehouse + ETL | True real-time with webhooks | High initial, low ongoing | Enterprise (>5000 orders/day) |
| Third-party Services | Varies by provider | Low | Non-technical teams |
As this analysis from a recent CData comparative review shows, enterprise-level operations requiring true real-time data will ultimately need to invest in a dedicated data warehouse with an ETL (Extract, Transform, Load) pipeline. This architecture, while having the highest initial setup cost, offers the most scalability and control, forming the backbone of a genuinely executable data system.
Historical Lookback vs Predictive Forecasting: What Belongs on the Home Tab?
An effective dashboard must provide context, and the most important context is time. The debate over displaying historical data versus predictive forecasts on a primary dashboard is not an either/or question; a truly executable dashboard requires both, but presented with a clear visual hierarchy. Historical data provides the factual grounding—the « what happened »—while predictive analytics offer the crucial « what might happen, » allowing for proactive rather than reactive management.
The primary view should anchor the user with solid, undeniable historical performance. This is typically represented with solid line graphs showing key metrics over a relevant period, such as the last 30 or 90 days. This establishes the baseline reality. Superimposed on this historical data, predictive forecasts should be displayed as a visually distinct element, for example, using a dotted or dashed line. This visual separation is critical to prevent users from misinterpreting a forecast as a factual outcome.
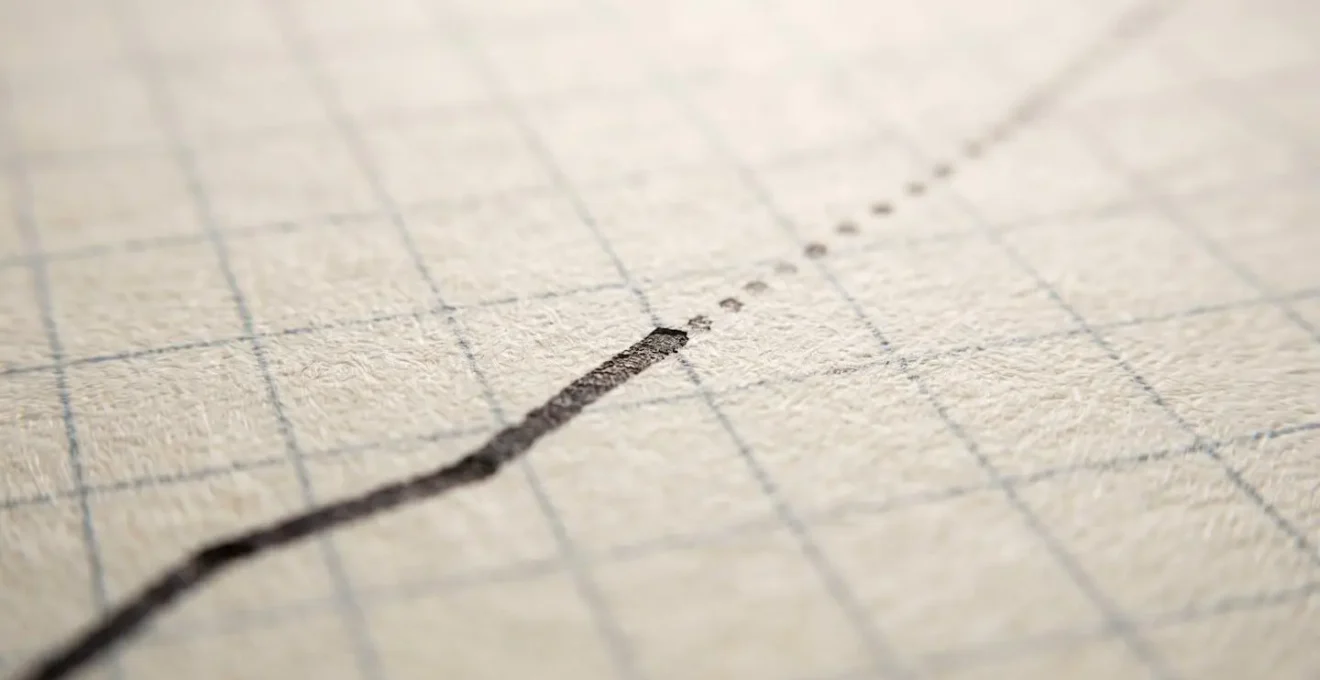
The real value of this combined view is not just in seeing the future trend, but in monitoring the variance between the forecast and actual performance as it unfolds. An executable system should include automated alerts that trigger when this variance exceeds a predefined threshold (e.g., 15%). These alerts are the « engine » part of the decision engine, transforming the dashboard from a passive chart into an active monitoring system that flags anomalies requiring executive attention. The ability to then drill down into the contributing factors of that variance is what enables rapid, targeted problem-solving.
The Vanity Metric Trap That Distracts Teams From Actual Profit Margins
The most pervasive error in e-commerce KPI management is the « vanity metric trap. » Metrics like total traffic, social media followers, or page views are easy to measure and often look impressive, but they rarely have a direct, causal relationship with profitability. An executive dashboard cluttered with these metrics distracts the entire organisation, incentivising teams to optimise for numbers that do not contribute to the bottom line. This creates a false sense of security and actively obscures the real drivers of financial health.
An executable dashboard ruthlessly prunes these vanity metrics from the primary view. The focus must shift to a structured Profit-Driver Hierarchy. This framework organises KPIs into tiers based on their proximity to net profit.
Case Study: FJ Solutions’ Profit-Driver Hierarchy
A leading e-commerce company, struggling with micromanagement and a lack of focus, worked with FJ Solutions to restructure their executive dashboards. They implemented a three-tier hierarchy. Tier 1 was limited to a single metric: Net Profit. Tier 2 displayed the direct drivers of profit: Customer Acquisition Cost (CAC), Customer Lifetime Value (CLV), and Gross Margin. Tier 3, accessible via drill-down, contained influencing levers like conversion rate and cart abandonment rate. By removing all other metrics from the executive view, the company refocused its teams on profitable actions. This led to a 7% increase in net profit and a 25% improvement in purchasing frequency within six months.
This hierarchical approach is the architectural antidote to the vanity metric trap. It forces a clear, logical line of inquiry. If net profit (Tier 1) is down, the director immediately examines the direct drivers in Tier 2. Is CAC too high? Is CLV falling? This structured diagnosis is impossible on a dashboard that presents 20+ metrics of equal visual weight. By architecting the dashboard around this hierarchy, you are not just displaying data; you are embedding a clear, profit-focused diagnostic workflow directly into the interface.
Fixing Data Refresh Delays That Cause Out-of-Stock Inventory Disasters
For an e-commerce operation, data latency is not a technical inconvenience; it is a direct threat to revenue and customer trust. A dashboard that displays inventory levels from six hours ago is worse than useless—it is dangerous. Decisions made on stale data lead directly to stockout disasters, where a popular item sells out while marketing campaigns continue to drive traffic to its product page. This wastes ad spend, frustrates customers, and damages brand reputation. An executable dashboard must be built on a foundation of near real-time data integrity.
The solution lies in moving away from periodic, batch-based data pulls and toward an event-driven architecture. This involves configuring the source system (e.g., Shopify) to actively push updates as they happen. The key technologies for this are webhooks. A webhook can be set up to trigger an alert every time an order is placed or an inventory level is changed. This alert, containing the data payload, is sent to a processing endpoint.
This architecture ensures that the data warehouse and, by extension, the Tableau dashboard, are updated within seconds or minutes of the actual event, not hours. It also enables the creation of highly valuable predictive KPIs like ‘Predicted Stockout Date,’ calculated by combining real-time sales velocity with current inventory levels. This transforms inventory management from a reactive process of reordering when stock is low to a proactive strategy of preventing stockouts before they occur.
Action Plan: Implementing Real-Time Inventory Tracking
- Set up Shopify webhooks for inventory level and new order events to push data instantly.
- Configure serverless functions (e.g., AWS Lambda) to receive and process webhook data into your data warehouse.
- Implement a ‘Predicted Stockout Date’ KPI using current sales velocity against remaining stock.
- Create automated alerts within your BI tool to notify stakeholders when stock levels for a key product drop below a 3-day supply threshold.
- Build an escalation workflow for critical stockout predictions (under 24 hours) that automatically flags the issue to purchasing and marketing heads.
Why Departmental Data Silos Cause Severe Billing Discrepancies?
An executable dashboard is only as reliable as the data that feeds it. Even with a perfect real-time pipeline, data integrity can be fundamentally corrupted before it ever reaches the dashboard. The most common source of this corruption is the existence of departmental data silos. This occurs when each department—marketing, sales, logistics, finance—operates on its own separate software and databases, with no single source of truth. Marketing uses its own CRM, finance has its ERP, and logistics operates a separate warehouse management system (WMS).
Organizations can no longer afford to have departments working in silos. They need to understand how all of their processes are working together.
– NetSuite Analytics Team, Ecommerce KPIs: Formulas, Benchmarks and Tips
This fragmentation inevitably leads to discrepancies. A classic example is in billing. The sales department may record a discount in their CRM that is not properly communicated to the finance department’s ERP. The customer is then billed the full amount, leading to disputes, costly manual reconciliation, and damage to customer relationships. Similarly, marketing might run a promotion based on data in their system, unaware that the logistics department’s WMS shows the item is nearly out of stock.
The solution is not just to pull data from these silos into a dashboard, but to break them down at an organisational level. This involves creating a unified data strategy and implementing ‘Bridge Metrics’—KPIs that are co-owned by multiple departments. For instance, ‘Order-to-Fulfillment Cycle Time’ is a metric that is jointly owned by sales and logistics. By making both departments accountable for this single number, it forces cross-departmental collaboration and process alignment. The Mote agency’s work with a Shopify partner demonstrated that this approach led to a reduction in billing discrepancies by over 30% by fostering shared accountability.
Why Manual Data Entry Between Departments Kills 30% of Qualified Leads?
Departmental data silos create another critical point of failure: the need for manual data entry. When a lead is captured by the marketing team’s system, it often needs to be manually transcribed into the sales team’s CRM. This process is not just slow; it is a primary source of data degradation and lost revenue. Each manual transfer introduces the risk of human error—a typo in an email address, an incorrect phone number, or a delay in transfer that allows a competitor to make first contact. Industry analysis suggests that as many as 30% of qualified leads can be lost or disqualified due to these entirely preventable manual data entry failures.
The latency introduced by this manual hand-off is lethal in a competitive market. A lead’s intent is highest in the moments after they submit a form. A delay of even a few hours can be the difference between a closed sale and a lost opportunity. An executable data system must therefore be designed to eliminate these manual touchpoints through automation. This is achieved by creating automated workflows using integration platforms like Zapier or Make, or through direct API connections between systems.
An effective dashboard can play a direct role in solving this. Instead of just displaying ‘Number of Leads,’ it should feature diagnostic metrics designed to monitor the health of the lead pipeline itself. Key metrics to implement include:
- Lead Response Time: A real-time widget showing the time delta between form submission and first contact by the sales team.
- Data Validation Failure Rate: A KPI that tracks how many leads are disqualified due to invalid contact information, directly measuring the cost of poor data quality.
- Potential Lost Revenue: A calculated metric that estimates the revenue lost from leads that were not contacted within a target timeframe.
By making the cost of manual data entry visible on the executive dashboard, it creates the organisational imperative to invest in automation.
Key Takeaways
- Decision paralysis is a direct result of cognitive overload; limit primary dashboard views to 3-5 core profit-driving KPIs.
- Data latency is a primary cause of operational failures like stockouts. An event-driven architecture using webhooks is essential for real-time integrity.
- Vanity metrics distract from profitability. A Profit-Driver Hierarchy (Net Profit > Direct Drivers > Influencing Levers) must be used to structure all KPI reporting.
Consolidating Fragmented Software Databases for UK Enterprise Operations
The ultimate architectural solution to the problems of data silos, manual entry, and latency is a formal data consolidation strategy. For any UK enterprise-level e-commerce operation, relying on a patchwork of disconnected departmental software is not a scalable or sustainable model. The end goal is to create a single, unified source of truth from which all analytics and operational dashboards are fed. This ensures that every department—from marketing to finance—is operating from the same, consistent data set.
An analysis by Forrester Research found that between 60% and 73% of all data within an enterprise goes unused for analytics. This is the direct result of fragmented, inaccessible data.
– Forrester Research
There are several high-level architectures for achieving this consolidation, each with different implications for cost, implementation time, and data latency. The choice depends on the organisation’s specific needs for data freshness and its in-house technical capabilities.
| Architecture Type | Implementation Time | Data Latency | Maintenance Effort |
|---|---|---|---|
| Central Data Warehouse | 3-6 months | 15-60 minutes | Medium |
| Real-time Data Lake | 6-9 months | Near real-time | High |
| Federated Query System | 1-3 months | Real-time | Low |
| Managed ETL Platform | 2-4 weeks | 5-15 minutes | Very Low |
While a full Real-time Data Lake represents the gold standard for data-intensive enterprises, a managed ETL platform offers a highly effective and rapid path to consolidation for many UK businesses. These platforms provide pre-built connectors for hundreds of software systems (Shopify, NetSuite, Salesforce, etc.) and handle the complexities of data extraction, transformation, and loading into a central warehouse. This dramatically lowers the barrier to creating a single source of truth, enabling the creation of truly reliable and executable KPI dashboards.
The next logical step for any e-commerce director or COO is to commission a formal audit of their current data architecture. This audit should evaluate systems not on the volume of data they produce, but on their structural integrity, latency, and the degree to which they enable—or hinder—clear, profitable, and immediate action.