Successful algorithmic fault detection is not about purchasing a black-box AI solution; it is about mastering the engineering discipline of data integrity and model validation.
- UK manufacturers must quantify failure costs beyond simple repairs, including specific factors like retailer penalties and Brexit-impacted supply chains.
- The choice between detection methods, such as acoustic versus thermal analysis, depends entirely on the specific factory environment and targeted failure modes.
Recommendation: Begin by establishing a rigorous, UKAS-compliant sensor calibration protocol and a human-in-the-loop validation process to build operational trust and avoid costly false positives.
The sudden, jarring silence of a production line grinding to a halt is a sound every plant manager dreads. It’s the prelude to a cascade of frantic phone calls, cascading delays, and costs that spiral with every passing minute. For too long, UK heavy manufacturing has been caught in this cycle of firefighting, a reactive loop of breakdown, diagnosis, and emergency repair. The conversation around Industry 4.0, AI, and predictive maintenance often promises a silver bullet, a future where machines fix themselves. But this simplistic view overlooks a crucial reality.
While the tools of the trade—vibration sensors, thermal cameras, and sophisticated algorithms—are more accessible than ever, they are not magic. Many organisations invest in the technology only to be disappointed by a deluge of false alarms or models that fail to predict the one critical failure that brings the entire operation to its knees. The common advice to « collect more data » is dangerously incomplete if the underlying processes are flawed.
The true shift from reactive to predictive maintenance is not a technological leap but a strategic and cultural one. It requires moving beyond the buzzwords and embracing a rigorous engineering discipline. The key lies not in the sophistication of the AI, but in the integrity of the data it consumes, the meticulous calibration of the sensors that provide it, and a clear-eyed financial justification for every step. It’s about building a system of trust between man and machine, where data augments, rather than replaces, human expertise.
This article provides a practical blueprint for UK plant and maintenance directors. It moves beyond the theoretical to dissect the real-world challenges and opportunities of implementing algorithmic fault detection. We will explore the true costs of inaction, the foundational steps for building a reliable data pipeline, the common traps to avoid, and the quantifiable rewards of getting it right.
Contents: A Blueprint for Algorithmic Fault Detection
- Why Run-to-Failure Strategies Cost Three Times More Than Algorithmic Prevention?
- How to Calibrate Vibration Sensors on High-Speed Production Lines?
- Acoustic vs Thermal Imaging: Which Detects Motor Degradation Faster?
- The False Positive Trap That Triggers Unnecessary Factory Shutdowns
- Eliminating Unplanned Downtime Using Machine Learning Maintenance Models
- Why Delaying Smart Factory Investments Increases Energy Waste by 25%?
- The Micro-Stop Ignorance That Quietly Steals 15% of Daily Capacity
- Maximising Overall Equipment Effectiveness in Food and Beverage Processing
Why Run-to-Failure Strategies Cost Three Times More Than Algorithmic Prevention?
The « run-to-failure » approach is not a strategy; it is a significant, and often unmeasured, financial liability. The direct costs of a breakdown are merely the tip of the iceberg. The true expense lies in the compounding impact of unplanned downtime, which can reach catastrophic levels. In the manufacturing sector, these costs can be staggering, with some reports citing figures as high as $260,000 per hour of downtime for a critical production line.
For UK-based manufacturers, this figure is amplified by a unique set of regional pressures. Beyond the immediate costs of emergency labour and expedited parts—often subject to a 15-25% premium due to post-Brexit supply chain friction—there are substantial downstream penalties. Failure to meet delivery commitments to major UK retailers like Tesco or M&S can trigger penalties ranging from £5,000 to £50,000 per incident. This financial pain is compounded by regulatory risk. A catastrophic failure could lead to an investigation by the Health and Safety Executive (HSE) for non-compliance with PUWER 98 (Provision and Use of Work Equipment Regulations 1998), which can result in unlimited fines and director-level prosecution.
Furthermore, failing equipment operates inefficiently. A degraded machine can consume 25-40% more energy, directly increasing a company’s liability under the Climate Change Levy (CCL). Algorithmic prevention transforms these unpredictable, cascading costs into a manageable, predictable operational expense. It shifts the focus from costly reaction to proactive, data-driven intervention, turning maintenance from a cost centre into a strategic driver of profitability and resilience.
How to Calibrate Vibration Sensors on High-Speed Production Lines?
If algorithmic fault detection is the goal, then data integrity is the non-negotiable foundation. A machine learning model is only as reliable as the data it is trained on. In the context of heavy manufacturing, this begins with the meticulous calibration of the very sensors that act as the system’s nervous system. An uncalibrated or improperly installed vibration sensor does not just provide inaccurate data; it provides actively misleading data, poisoning the well for any subsequent analysis and leading to a catastrophic loss of trust in the system.
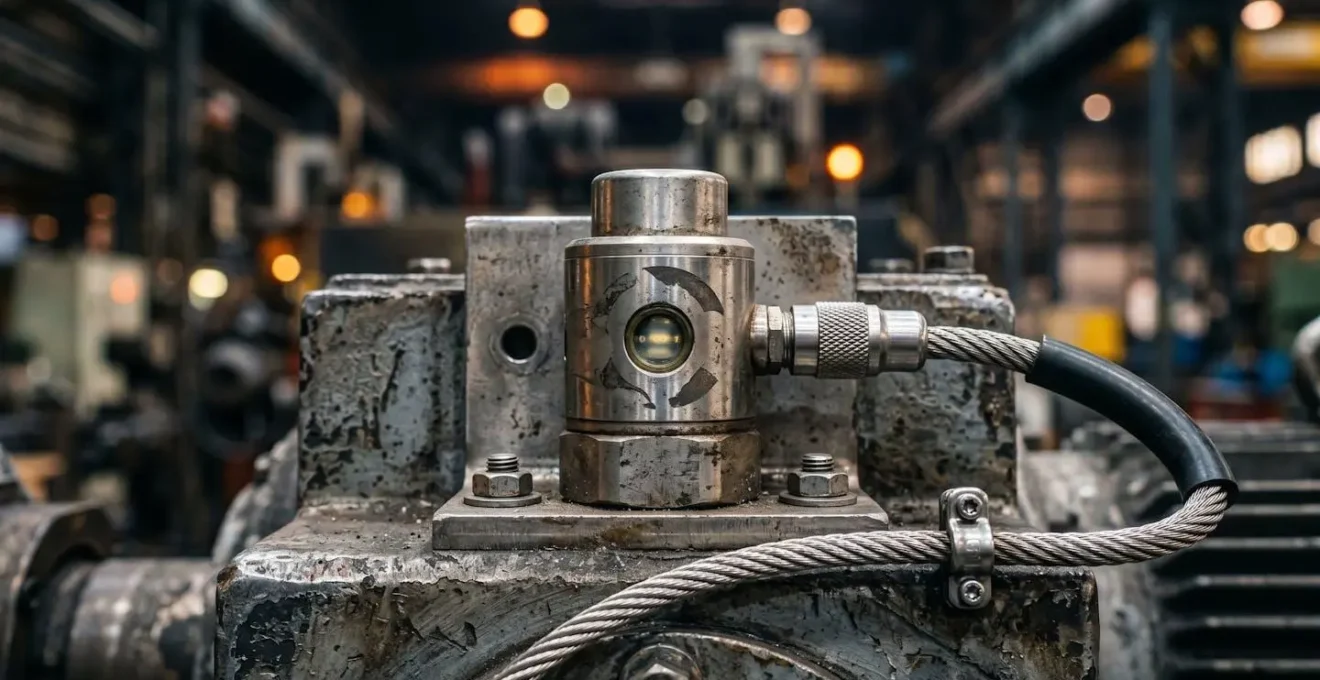
In the UK, the standard for metrology is exceptionally high. Calibration must be traceable to national standards, a service provided by the National Physical Laboratory (NPL) and its network of UKAS-accredited laboratories. For any predictive maintenance programme to be credible, especially for businesses in regulated supply chains like aerospace or automotive, adhering to ISO 17025 calibration standards is not optional. This ensures that a reading of ‘X’ on your dashboard corresponds precisely to a known physical vibration, forming the bedrock of reliable diagnostics.
The process of maintaining this integrity is a continuous discipline, not a one-off task. It involves a strategic blend of scheduling, documentation, and personnel training, leveraging UK-specific frameworks to ensure compliance and competence. Implementing a robust calibration strategy is the first, most critical step in building a trustworthy fault detection system.
Your Action Plan: UK-Compliant Sensor Calibration
- Identify & Partner: Locate and establish a relationship with a UKAS-accredited laboratory for routine calibration. Use the NPL for primary standards and regional labs like Lambda Calibration for scheduled services.
- Define Frequency: Establish a calibration schedule based on compliance needs. At minimum, follow ISO 9001’s annual requirement, but for critical automotive or aerospace lines, adopt a more rigorous 6-month interval.
- Maintain an Audit Trail: Prepare and meticulously maintain all calibration documentation. This is essential for ISO 9001 certification audits and proving compliance within stringent UK supply chains.
- Upskill Your Team: Leverage the Apprenticeship Levy to access government-funded training. Empower your BTEC or City & Guilds qualified staff with specialised skills in sensor metrology and data verification.
- Develop a Hybrid Strategy: Implement a two-tiered approach. Utilise on-site calibration services for the most critical production lines to minimise downtime, and schedule off-site calibration for less critical assets during planned maintenance periods.
Acoustic vs Thermal Imaging: Which Detects Motor Degradation Faster?
Once a reliable data pipeline is established, the next strategic decision is selecting the right detection methodology. The two most common non-contact methods for monitoring rotating machinery like motors are thermal imaging and acoustic analysis. The choice is not about which technology is « better » in the abstract, but which is more effective for detecting specific failure modes within your unique factory environment. Both have distinct advantages and limitations, particularly within the context of UK manufacturing facilities, which often blend modern automation with legacy infrastructure.
Thermal imaging provides an instantaneous snapshot of a machine’s heat signature. It excels at identifying issues related to friction, cooling-system failures, or electrical resistance before they become critical. However, its effectiveness can be compromised in the cold, damp, and variable ambient temperatures common in many UK factories, which can make it difficult to establish a stable thermal baseline. Acoustic analysis, conversely, listens for high-frequency sound waves characteristic of bearing wear, material impacts, or gas leaks. It can be highly effective even in noisy legacy production halls, as algorithms can be trained to filter out background noise and focus on the specific sonic signature of a developing fault.
Case Study: West Midlands Automotive Supplier Pilot
A UK automotive supplier conducted a three-month pilot comparing thermal cameras from Flir UK distributors against an acoustic monitoring system on a critical production cell. The acoustic system successfully detected the subtle signs of bearing degradation in a robotic arm three weeks before any discernible thermal signature appeared. This early warning prevented a catastrophic failure that would have halted production and jeopardized their Tier 1 supply contract with Jaguar Land Rover, demonstrating a clear return on investment within six months purely through avoided downtime.
The optimal choice often depends on a cost-benefit analysis and the specific failure modes you aim to detect. For many UK SMEs, a pilot project combining both technologies on a single critical asset can provide the most comprehensive coverage and deliver invaluable data to inform a wider rollout strategy.
| Detection Method | UK Environment Suitability | Detection Speed | Cost (UK SME) | Cost (Large Corp) |
|---|---|---|---|---|
| Thermal Imaging | Challenging in cold/damp UK factories | Instant temperature anomalies | £5,000-15,000 rental/year | £50,000-150,000 permanent |
| Acoustic Analysis | Effective despite noisy legacy halls | 2-4 weeks pattern recognition | £8,000-20,000 rental/year | £100,000-300,000 multi-point |
| Combined Approach | Optimal for variable UK conditions | Comprehensive coverage | £12,000-30,000 pilot project | £150,000-400,000 full system |
The False Positive Trap That Triggers Unnecessary Factory Shutdowns
One of the greatest barriers to the adoption of algorithmic fault detection is the fear of the « false positive »—an alert that triggers a costly, unnecessary shutdown. This fear is not unfounded. Early-phase deployments of industrial AI systems can be prone to misinterpretation, with some Industry 4.0 fault detection research indicating a 15-30% false positive rate as models are initially learning the nuances of a specific operational environment. An AI that cries wolf too often will quickly be ignored or disabled, completely undermining the investment and eroding trust between the engineering team and the technology.
The solution is not to abandon the technology, but to build a robust human-in-the-loop validation process. This approach treats the AI not as an infallible oracle, but as a powerful screening tool for an experienced maintenance engineer. Instead of triggering an automatic shutdown, the AI’s alert is routed to a senior engineer for review, armed with the contextual data that led to the prediction. This empowers the engineer to make the final call, combining their years of experience with the algorithm’s analytical power. As one research team noted, this synergy is essential:
FDD [Fault Detection and Diagnosis] is a core function to ensure manufacturing systems are reliable, efficient, and safe in today’s sector.
– Industry 4.0 Research Team, Frontiers in Mechanical Engineering
A crucial strategy for building this trust is to run the AI in « shadow mode » for an initial period of 3-6 months. The system makes predictions but triggers no actions, simply logging its findings. This allows the team to validate the model’s accuracy against reality without operational risk. Crucially in the UK context, this implementation phase must also involve open dialogue with trade union representatives, framing the technology as a tool for worker empowerment and safety, not a mechanism for replacing skilled jobs. By establishing a clear escalation matrix and validation workflow, you transform the false positive from a system-breaking trap into a valuable learning opportunity.
Eliminating Unplanned Downtime Using Machine Learning Maintenance Models
With a foundation of calibrated sensors and a human-centric validation process, machine learning (ML) models can evolve from simple alert systems into powerful engines for eliminating unplanned downtime. By analysing historical data from thousands of operational cycles, these models learn the subtle, multi-variate signatures that precede a failure, often detecting correlations that are invisible to the human eye. This capability moves maintenance from a calendar-based schedule to a condition-based, « just-in-time » intervention model.
The impact of this shift is transformative. According to extensive McKinsey research on AI predictive maintenance, successful implementations can lead to a 40% reduction in maintenance costs and a staggering 50% decrease in total downtime. These are not just theoretical numbers; they are being realised today in UK factories.
Case Study: UK Automotive Supplier’s ML Breakthrough
A Tier 1 automotive supplier in the West Midlands, with a project co-funded by Innovate UK’s Made Smarter programme, deployed an ML-based system using edge AI and private 5G networks. The system analyses data from their robotic assembly lines in real-time. Within the first year, the model predicted critical robotic arm failures with 92% accuracy, preventing three potential line stoppages that would have each cost the company over £1 million in lost production and penalties. The project delivered a 2.6x return on investment within just 12 months, proving the immense financial viability of the technology when implemented correctly.
This level of success is not achieved overnight. It is the culmination of mastering the preceding steps: ensuring data integrity, choosing the right sensors, and building a culture of trust in the system’s outputs. When these elements are in place, machine learning becomes the strategic lever that moves a manufacturing operation from a state of constant reaction to one of control, predictability, and continuous improvement.
Why Delaying Smart Factory Investments Increases Energy Waste by 25%?
The connection between operational reliability and energy consumption is direct and financially significant. Degraded or inefficiently operated equipment is a major source of energy waste, a problem that has become a boardroom-level concern amid volatile UK energy markets. A machine operating outside its optimal parameters—due to bearing wear, poor lubrication, or incorrect settings—can consume significantly more power to achieve the same output. For a medium-sized UK manufacturer, this inefficiency is not a trivial matter. An estimated 25% energy waste can translate to a direct cost of £125,000 annually, based on current commercial electricity rates.
Delaying investment in smart factory technologies, such as algorithmic fault detection, means leaving this money on the table. The same IoT sensors and data streams used to predict mechanical failures are also perfect for monitoring asset-level energy consumption. This provides a granular, real-time view of where every kilowatt-hour is going, exposing the hidden costs of inefficiency.
This capability is no longer just a « nice-to-have » for cost reduction; it is becoming a matter of regulatory compliance. The UK’s Energy Savings Opportunity Scheme (ESOS) Phase 3 mandates that large undertakings conduct detailed energy audits and identify opportunities for improvement. Algorithmic monitoring systems provide the exact asset-level data required to automate ESOS reporting and, more importantly, to action the identified savings. Investing in this technology acts as a hedge against future energy price volatility and Carbon Price Support (CPS) increases, locking in efficiency gains and turning a compliance burden into a competitive advantage. UK government initiatives like Made Smarter and Innovate UK often provide grants covering up to 50% of implementation costs, significantly lowering the barrier to entry.
The Micro-Stop Ignorance That Quietly Steals 15% of Daily Capacity
While plant managers are acutely aware of the impact of a full-line stoppage, a far more insidious and often-ignored issue is the « micro-stop. » These are the brief, sub-minute interruptions that plague high-speed lines in sectors like food and beverage or automotive parts. A conveyor jams for three seconds, a packaging machine misfeeds for five—each incident is too short to warrant a formal downtime log and is often resolved by an operator on the spot. Individually, they seem insignificant. Cumulatively, they are a catastrophic drain on capacity.
Because they are not formally tracked, their true impact remains hidden. The standard Overall Equipment Effectiveness (OEE) calculation often fails to capture this loss, leading to a dangerously inflated view of plant performance. In the fast-moving consumer goods (FMCG) sector, it’s not uncommon for these micro-stops to silently steal 15-18% of a line’s theoretical daily capacity. The financial consequences are severe, representing hundreds of thousands of pounds in lost production and missed delivery slots over a year.
Case Study: The UK Biscuit Factory’s £180,000 Discovery
A UK biscuit manufacturer was struggling to meet supermarket demand despite OEE figures suggesting they had ample capacity. By retrofitting their packaging line’s Allen-Bradley PLCs with IoT gateways, they began to analyse high-frequency operational data. The analysis revealed that 3-second micro-stops were occurring 240 times per shift, totaling 12 minutes of lost production each day. Over a year, this equated to 52 hours of lost capacity, worth £180,000 in missed revenue. The machine learning model went further, correlating the stops with humidity fluctuations in their Victorian-era building, identifying a root cause that had been invisible for decades.
Micro-stops are a classic « unknown unknown. » You cannot manage what you do not measure. Algorithmic monitoring, with its ability to analyse data at a millisecond resolution, is the only effective way to bring this hidden factory of lost time to light. It transforms anecdotal operator observations into hard, quantifiable data, providing the first critical step toward resolving these deep-seated, capacity-killing problems.
Key Takeaways
- Run-to-failure is not a strategy; it is a quantifiable liability that can cost over $260,000 per hour, a figure amplified by UK-specific factors like retailer penalties and supply chain friction.
- Data integrity is the absolute bedrock of success. AI models are useless without rigorously calibrated sensors (to UKAS standards) and a human-in-the-loop validation process to combat the typical 15-30% false positive rate in early deployments.
- True operational excellence comes from tackling granular issues. Algorithmic monitoring exposes hidden losses like micro-stops and energy waste, which can quietly erode up to 15% of a plant’s total capacity.
Maximising Overall Equipment Effectiveness in Food and Beverage Processing
While the principles of algorithmic fault detection are universal, their application in the UK’s food and beverage sector highlights their power in maximising the ultimate metric: Overall Equipment Effectiveness (OEE). In an industry governed by tight margins, stringent Food Standards Agency (FSA) compliance, and the immense pressure of supermarket supply contracts, OEE is not just a performance indicator; it is a measure of survival. Here, predictive technologies are crucial for balancing the competing demands of productivity, safety, and efficiency. Organisations that successfully implement predictive maintenance (PdM) in this sector report a dramatic impact, including a 55% reduction in unplanned equipment failures.
Consider the critical Clean-in-Place (CIP) process in a dairy. A failure here not only halts production but also carries a massive contamination risk, potentially leading to product recalls and delistings from major retailers. Using ML models to analyse pump pressures and valve responses allows processors to optimise CIP cycles, reducing chemical, water, and energy usage while maintaining full FSA compliance. One UK dairy used this approach to reduce energy costs by £45,000 annually and, crucially, ensured zero CIP-related failures during the critical Easter peak production period, guaranteeing 100% delivery performance.
The goal is to create a fully integrated system where predictive alerts are linked directly to quality management systems, providing an automatic audit trail for compliance. ML models can be trained to account for the unique seasonal demand patterns of the UK market, such as Christmas and Easter production peaks, ensuring that maintenance is scheduled proactively before these high-stakes periods. By focusing on critical control points like seal integrity and CIP cycles, food and beverage manufacturers can use algorithmic monitoring to move beyond simple failure prevention and toward true process optimisation, driving OEE to world-class levels.
Your first step is not to purchase a new software suite, but to benchmark your current operational maturity. Use the principles outlined in this guide to conduct an initial audit of your sensor data integrity, document your validation processes, and, most importantly, calculate your own true, fully-loaded cost of unplanned downtime.